BestLLMfor
Tells you which open-weight LLMs will run on your PC or Mac
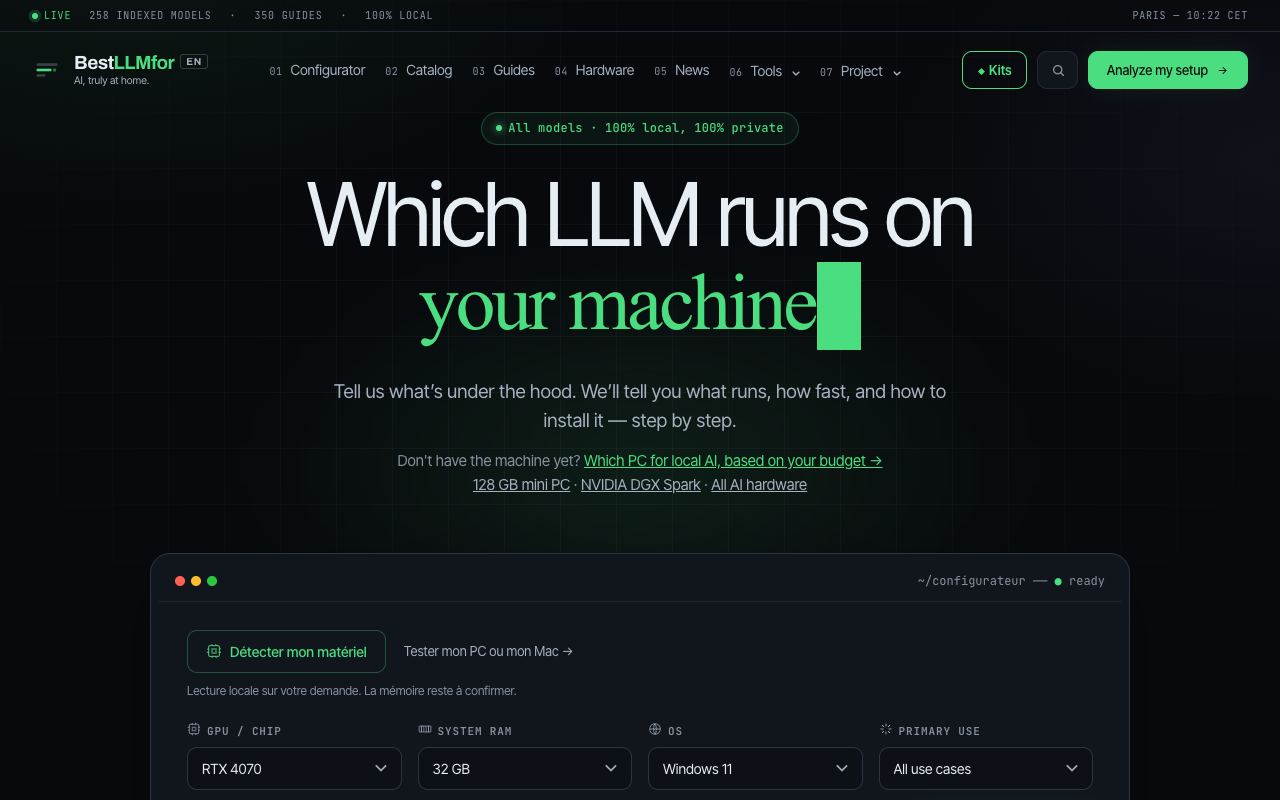
BestLLMfor is a guide to running language models on your own hardware. Its configurator takes your GPU or Apple Silicon chip, system RAM, operating system and intended use, and returns the open-weight models that fit, with their memory needs and expected speed. The hardware scan runs in your browser when you ask for it, and the site recommends confirming the memory figure by hand.
Highlights
- A configurator that matches models to a GPU or Apple chip, RAM, OS and a use case such as chat, coding, RAG, vision, audio or agents
- A model catalog with parameter count, VRAM needed at Q4 quantization, context length and estimated tokens per second
- Rankings by use, for example coding, RAG, machines without a GPU or models licensed for commercial use
- Install guides for Ollama and LM Studio, plus hardware advice by budget
- A news feed on open-weight model releases
- Paid kits per setup (local coding assistant, local RAG, local agents, Mac, image generation and more) at $24 each or $49 for all
Good to know
- The configurator, catalog and guides need no account
- Speed and memory figures are estimates; test on your own machine before buying hardware
- The same team publishes a French edition (QuelLLM) and an Italian one (QualeLLM)
For people choosing a model to run locally, or a machine to run it on. The core tools are free and the kits are one-time purchases.
Similar tools
See alternatives →
Scro
PaidBuilds an AI influencer with a locked face, wardrobe and your voice

Vectoree
FreemiumOne backend for coding agents: model gateway, auth, Postgres and storage
Novastart
FreemiumA desktop on an infinite canvas, shared with teammates and AI agents
Comments(0)
Sign in to comment